The Signal · From the workshop
Building an open India AI Index
An open harness that tests how language models handle Indian languages and Indian paperwork, and what each task costs in rupees. It has not scored a single model yet, and that is deliberate.
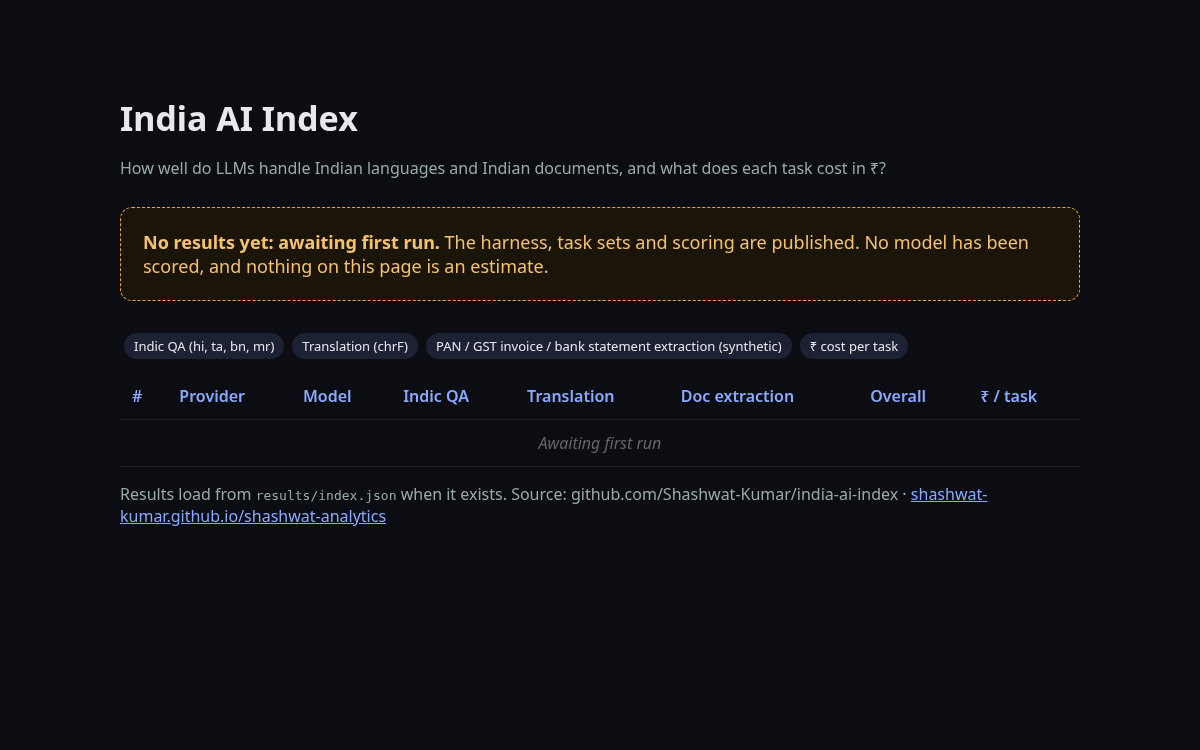
This is a project I built. Code is MIT-licensed and open for review.
What it is
India AI Index is an open-source benchmark harness. It sends the same tasks to different models: short questions in Hindi, Tamil, Bengali and Marathi, English-to-Indic translation, and reading a PAN card, a GST invoice or a bank statement into structured fields. It scores the answers and records the cost of each task in rupees. Providers are plug-ins for OpenAI, Google, Anthropic, xAI, Sarvam and open models via Hugging Face, with API keys read from the environment.
Why it matters
Most public leaderboards measure English. A team building for Indian customers needs different answers: does the model get Marathi right, can it read an invoice, and what does that cost per document in ₹, not per million tokens in dollars? A shared, re-runnable test set is the only honest way to compare. Prices and exchange rates change, so the harness takes both at run time and stores them with every result.
Honest caveats
No results yet. No model has been run, and the leaderboard says “awaiting first run” rather than showing estimates. The first task set is small (29 items), meant to prove the pipeline. Every document is synthetic, with fictional names and IDs that are invalid by design. I wrote the reference translations myself, and they need review by native speakers before any score should be quoted.
Try it
Code, tests and quickstart: github.com/Shashwat-Kumar/india-ai-index. Issues and pull requests are welcome.